Back to walidsassi.com
Scoring a multimodal receipt extraction with code metrics and a model judge

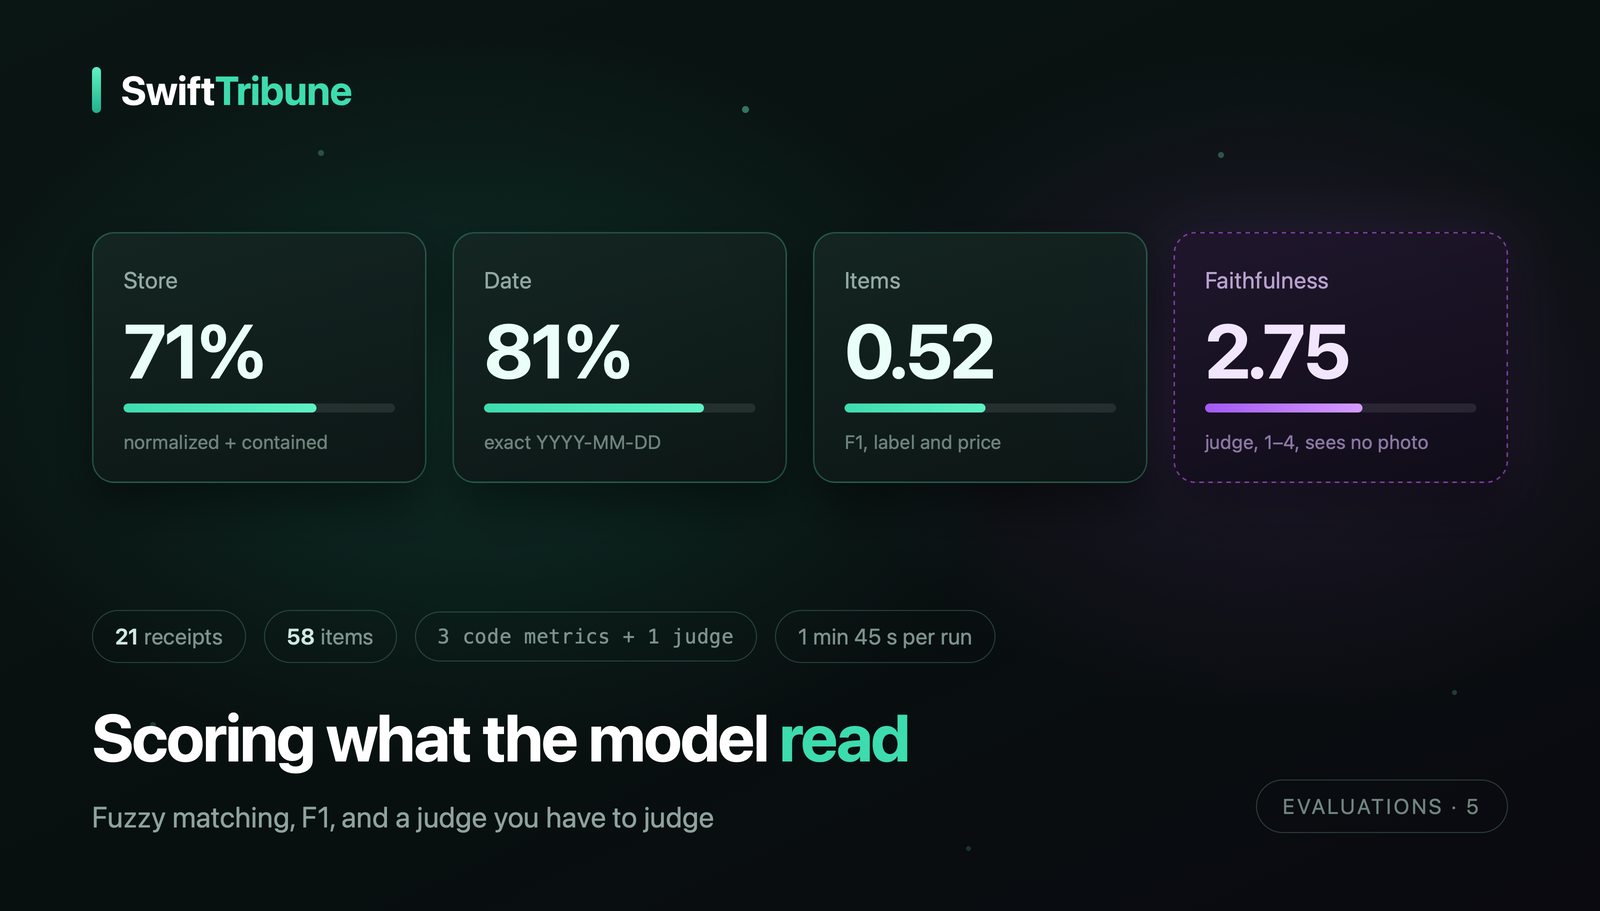
Scoring What the Model Read: Metrics, a Judge, and 21 Receipts

Comparing store names with == fails almost every receipt. Here are the three code metrics and the model judge that turn a photo extraction into numbers, plus the results on 21 real receipts and the error patterns hiding behind them.
September 12, 2026 · 10 min · Walid Sassi
Reading a store receipt photo with Apple's multimodal on-device model

When the Model Can See: Reading Receipts with Multimodal Prompting

Multimodal prompting collapses OCR and understanding into one call. Here is the feature: a @Generable Receipt, one carefully shaped session with an image Attachment, and the photo dataset that has to be transcribed by hand before anything can be measured.

September 12, 2026 · 9 min · Walid Sassi
Refining a model-as-judge evaluator in Apple's Evaluations framework

Two Refinements That Sharpen a Model-as-Judge Evaluator

Two refinements to the NeighborhoodCoherence judge from part two: pass the metric name straight to ModelJudgeEvaluator to drop the ScoreDimension boilerplate, and shape what the judge actually reads with evaluationTarget and reference.

August 19, 2026 · 7 min · Walid Sassi
When code can't judge quality: model-as-judge evaluators in Swift

When Code Can't Judge Quality: Model-as-Judge Evaluators in Apple's Evaluations Framework

Code-based evaluators can only measure what code can measure. This companion article goes deep on ModelJudgeEvaluator: choosing a scoring scale, writing scoring levels that actually work, and wiring a model-as-judge into the TripPlanner evaluation from part one.

July 26, 2026 · 7 min · Walid Sassi
Apple's Evaluations framework: testing non-deterministic Foundation Models features

Testing the Untestable: A Deep Dive into Apple's Evaluations Framework

How to test generative, non-deterministic features with Apple’s Evaluations framework, the five steps of an evaluation, datasets and the Loader protocol, synthetic sample generation, evaluators and metrics, and the compiler gotchas hit along the way.

July 19, 2026 · 22 min · Walid Sassi
Claude Agents in Claude Code, the new agent view for multi-agent iOS workflows

Claude Agents: Multi-Agent iOS Workflows in Claude Code

A walkthrough of Anthropic’s new Claude Agents (agent view) inside Claude Code on iOS: how to run a Clean Architecture refactor agent and a unit-testing agent in parallel on isolated Git worktrees, with the full lifecycle and synchronisation pitfalls.

May 13, 2026 · 12 min · Walid Sassi