Back to walidsassi.com
iOS · Swift · AI

Engineering-grade iOS, from architecture to AI.

SwiftTribune is a technical platform for iOS engineers who take software craft seriously. In-depth articles, tips, and podcast conversations on the decisions that make apps scalable, testable, and built to last, from Swift 6 Concurrency to on-device AI.
Swift 6 Concurrency Clean Architecture On-device AI SwiftUI iOS at Scale
iOS Swift Tips AI Dev Podcast
New Book · Packt Publishing

AI-Driven Swift
Architecture

Master scalable iOS architecture in the AI era

Scoring a multimodal receipt extraction with code metrics and a model judge

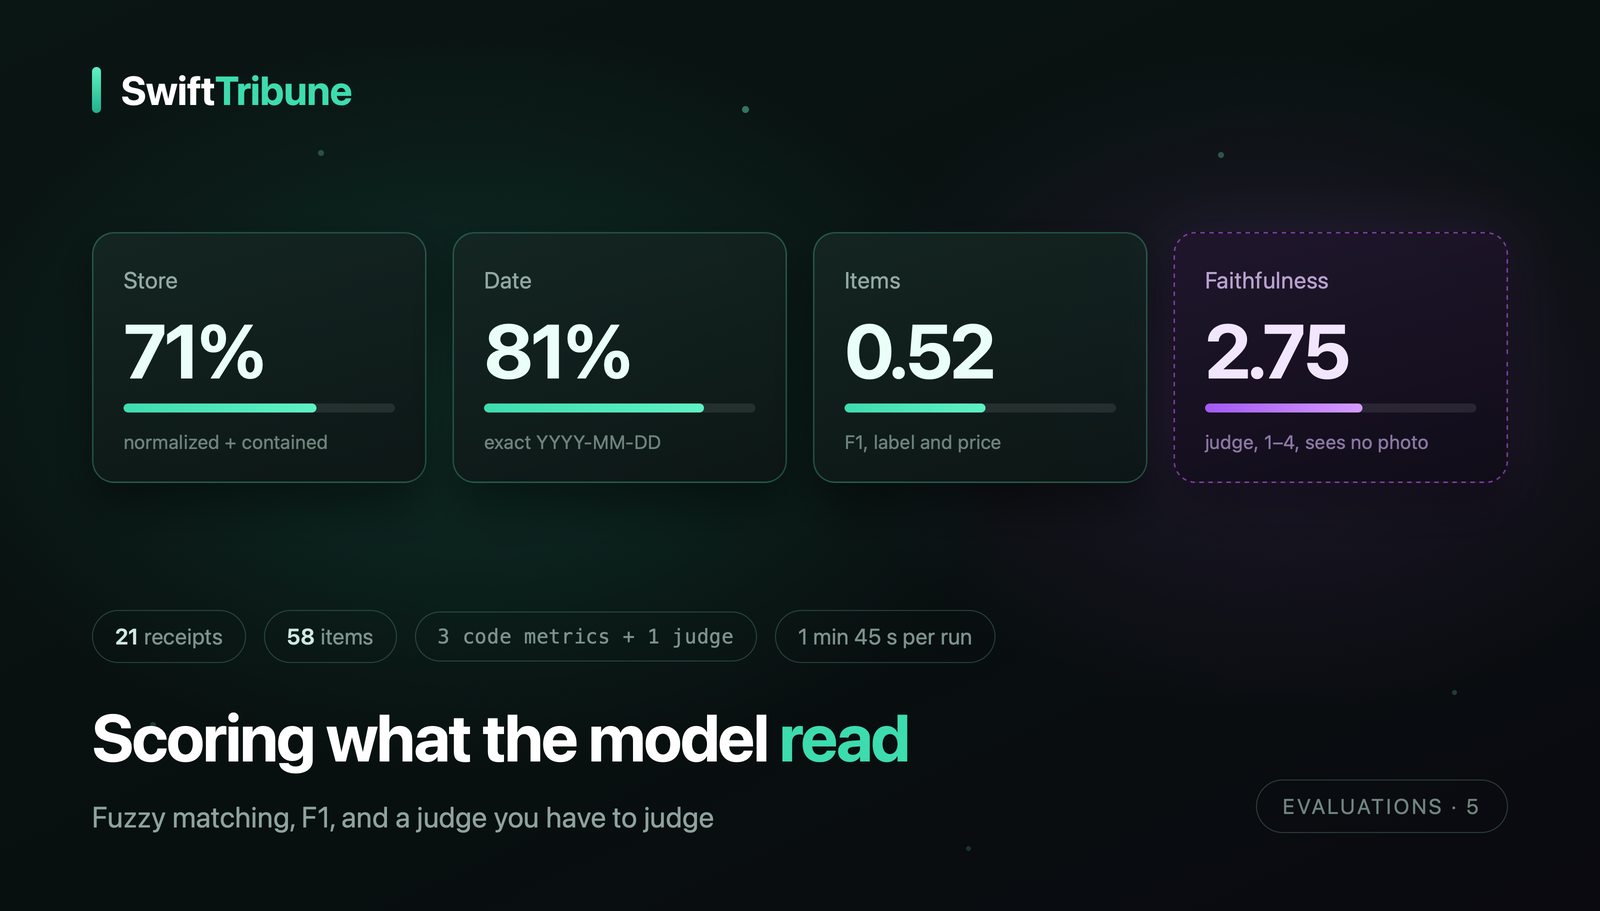
Scoring What the Model Read: Metrics, a Judge, and 21 Receipts

Comparing store names with == fails almost every receipt. Here are the three code metrics and the model judge that turn a photo extraction into numbers, plus the results on 21 real receipts and the error patterns hiding behind them.

September 12, 2026 · 10 min · Walid Sassi
Reading a store receipt photo with Apple's multimodal on-device model

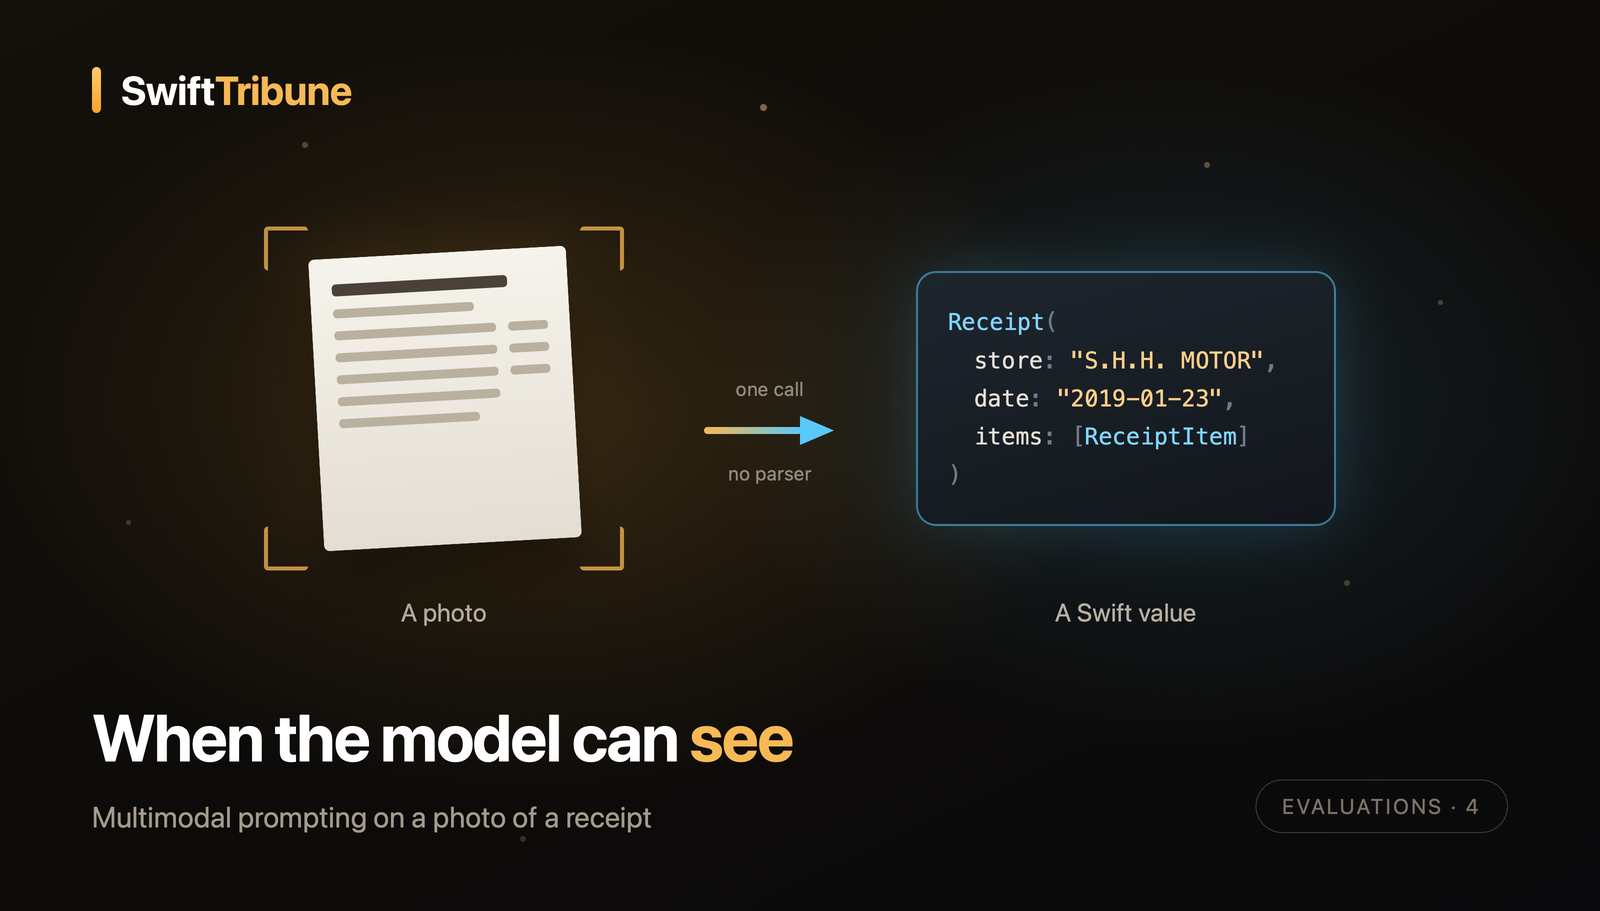
When the Model Can See: Reading Receipts with Multimodal Prompting

Multimodal prompting collapses OCR and understanding into one call. Here is the feature: a @Generable Receipt, one carefully shaped session with an image Attachment, and the photo dataset that has to be transcribed by hand before anything can be measured.

September 12, 2026 · 9 min · Walid Sassi
Refining a model-as-judge evaluator in Apple's Evaluations framework

Two Refinements That Sharpen a Model-as-Judge Evaluator

Two refinements to the NeighborhoodCoherence judge from part two: pass the metric name straight to ModelJudgeEvaluator to drop the ScoreDimension boilerplate, and shape what the judge actually reads with evaluationTarget and reference.

August 19, 2026 · 7 min · Walid Sassi
When code can't judge quality: model-as-judge evaluators in Swift

When Code Can't Judge Quality: Model-as-Judge Evaluators in Apple's Evaluations Framework

Code-based evaluators can only measure what code can measure. This companion article goes deep on ModelJudgeEvaluator: choosing a scoring scale, writing scoring levels that actually work, and wiring a model-as-judge into the TripPlanner evaluation from part one.

July 26, 2026 · 7 min · Walid Sassi
Apple's Evaluations framework: testing non-deterministic Foundation Models features

Testing the Untestable: A Deep Dive into Apple's Evaluations Framework

How to test generative, non-deterministic features with Apple’s Evaluations framework, the five steps of an evaluation, datasets and the Loader protocol, synthetic sample generation, evaluators and metrics, and the compiler gotchas hit along the way.

July 19, 2026 · 22 min · Walid Sassi
Running large language models locally on Apple Silicon

Local LLMs on Apple Silicon, Part 1: From Compatibility to Your First Local Chat

Cloud APIs put a frontier model behind a single HTTPS call. That convenience is hard to beat, and for most production workloads it remains the right choice. But something has shifted over the last couple of years: the gap between “what a hosted model can do” and “what a model running on your laptop can do” has narrowed enough that local inference is no longer a curiosity. For developers, especially those of us building on Apple Silicon, it has become a serious option. ...

May 21, 2026 · 19 min · Walid Sassi
Claude Agents in Claude Code, the new agent view for multi-agent iOS workflows

Claude Agents: Multi-Agent iOS Workflows in Claude Code

A walkthrough of Anthropic’s new Claude Agents (agent view) inside Claude Code on iOS: how to run a Clean Architecture refactor agent and a unit-testing agent in parallel on isolated Git worktrees, with the full lifecycle and synchronisation pitfalls.

May 13, 2026 · 12 min · Walid Sassi
MLX Embedders, Text Embeddings on Apple Silicon with Swift

MLX Embedders in Swift: On-Device Text Embeddings for iOS

In Part 1 of this series, we built a minimal LLM inference pipeline on Apple Silicon using MLX Swift. In Part 2, we quantized a model from scratch and saw how 4-bit precision makes billion-parameter models tractable on a phone. This article introduces MLX Embedders, specifically the MLXEmbedders Swift library, and takes a different angle. Instead of generating text, we are going to encode meaning. A user types: “best hikes near a volcano.” A keyword search returns nothing useful. An embedding-based system returns exactly what they need, because it understands what the words mean, not just what they spell. That capability is what embeddings unlock, and it is the foundation of every serious AI feature in production today: semantic search, recommendation systems, RAG pipelines, and clustering. ...
April 24, 2026 · 19 min · Walid Sassi
Quantization in LLMs for mobile developers

Quantization in LLMs: How to Run AI on Your iPhone Without Burning It

In Part 1 of this series, we set up the MLX ecosystem and ran a language model locally on Apple Silicon. If you haven’t read it yet, it’s worth starting there. This article tackles the question that naturally follows: how do you fit a multi-billion parameter model into a device with 8 GB of RAM? The answer is quantization, and understanding it will change how you think about on-device AI. Introduction: LLMs Are Just Very Large Matrices Before we can explain quantization, we need to be clear about what we’re actually compressing. ...

April 6, 2026 · 10 min · Walid Sassi
MLX Swift, On-Device Large Language Models on Apple Silicon

MLX Swift: Enabling On-Device Large Language Models on Apple Silicon

Abstract The proliferation of large-scale neural language models has, until recently, been contingent upon access to remote computational infrastructure. The architectural characteristics of Apple Silicon, most notably its unified memory subsystem, present a substantive departure from this dependency. This article examines MLX Swift, a native Swift binding to Apple’s MLX machine learning framework, as a mechanism for deploying quantized Large Language Models (LLMs) directly on consumer Apple hardware. We characterize the layered architecture of the MLX ecosystem, contrast its design philosophy with that of Apple’s Foundation Models API, and present a reference implementation demonstrating the complete inference lifecycle: model acquisition, session initialization, and autoregressive text generation. The discussion is grounded in the computational properties of unified memory and their implications for on-device inference efficiency. ...

March 31, 2026 · 13 min · Walid Sassi