Back to walidsassi.com

Modern iOS Performance Myths with Artem Mirzabekian and Bogdan Poplauschi

Swift Academy Podcast, Episode 1, Season 3 Modern iOS Performance Myths Season 3 opens with a two-part conversation on performance, with Artem Mirzabekian and Bogdan Poplauschi. Part one is about the dogmas: what a fast app actually is, and why so many of them still feel slow. July 5, 2026 🎧 Swift Academy Podcast · Episode 1, Season 3 • Part 1 of 2 · Performance • SwiftUI • Concurrency Watch the Episode Fast Is Not the Same as Feeling Fast An application can be technically fast and still feel slow. That gap, between what a benchmark measures and what a user perceives, is where this episode spends most of its time. ...
July 5, 2026 · 3 min · Walid Sassi

Modern iOS Security: Attacks, Defenses & AI with Dave Poirier and Deya Elkhawaldeh

Swift Academy Podcast, Episode 12, Season 2 Modern iOS Security: Attacks, Defenses & AI Dave Poirier and Deya Elkhawaldeh on iOS security as an engineering culture problem rather than a tooling one, and on what AI has already changed for the people attacking your app. May 31, 2026 🎧 Swift Academy Podcast · Episode 12, Season 2 · Mobile Security • Attacker Mindset • AI Watch the Episode Why This One Matters “Apple handles security for us” is, according to both guests, the single most expensive misconception in iOS development. The platform gives you good defaults. It does not give you a threat model. ...

May 31, 2026 · 3 min · Walid Sassi
Running large language models locally on Apple Silicon

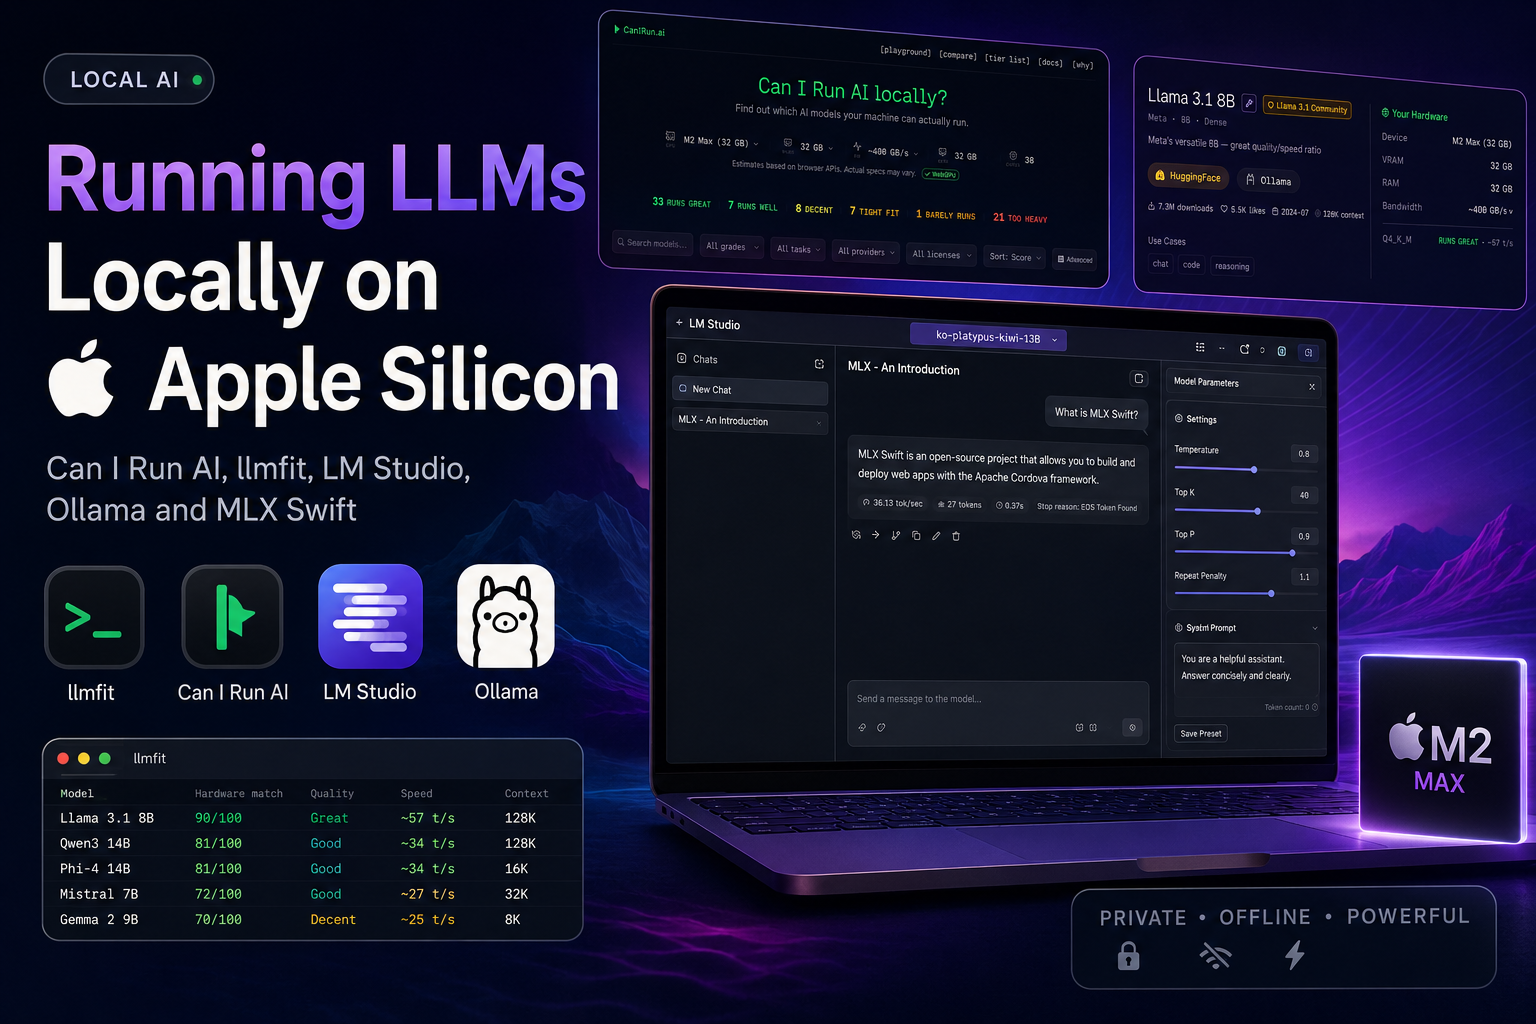
Local LLMs on Apple Silicon, Part 1: From Compatibility to Your First Local Chat

Cloud APIs put a frontier model behind a single HTTPS call. That convenience is hard to beat, and for most production workloads it remains the right choice. But something has shifted over the last couple of years: the gap between “what a hosted model can do” and “what a model running on your laptop can do” has narrowed enough that local inference is no longer a curiosity. For developers, especially those of us building on Apple Silicon, it has become a serious option. ...

May 21, 2026 · 19 min · Walid Sassi

MLX Swift & On-Device AI with Adrien Grondin

Swift Academy Podcast, Episode 11, Season 2 MLX Swift & On-Device AI Adrien Grondin, iOS developer at LM Studio and creator of Locally AI, on why Apple Silicon changes the economics of running language models locally, and where that stops being true. May 17, 2026 🎧 Swift Academy Podcast · Episode 11, Season 2 · MLX Swift • Local LLMs • Apple Silicon Watch the Episode Why This One Matters Most teams shipping AI features today send everything to a cloud API. That works until you look at the bill, the latency, or the privacy review. Meanwhile Apple has been quietly building the other path: a framework designed from the start for unified memory on Apple Silicon. ...

May 17, 2026 · 3 min · Walid Sassi
Claude Agents in Claude Code, the new agent view for multi-agent iOS workflows

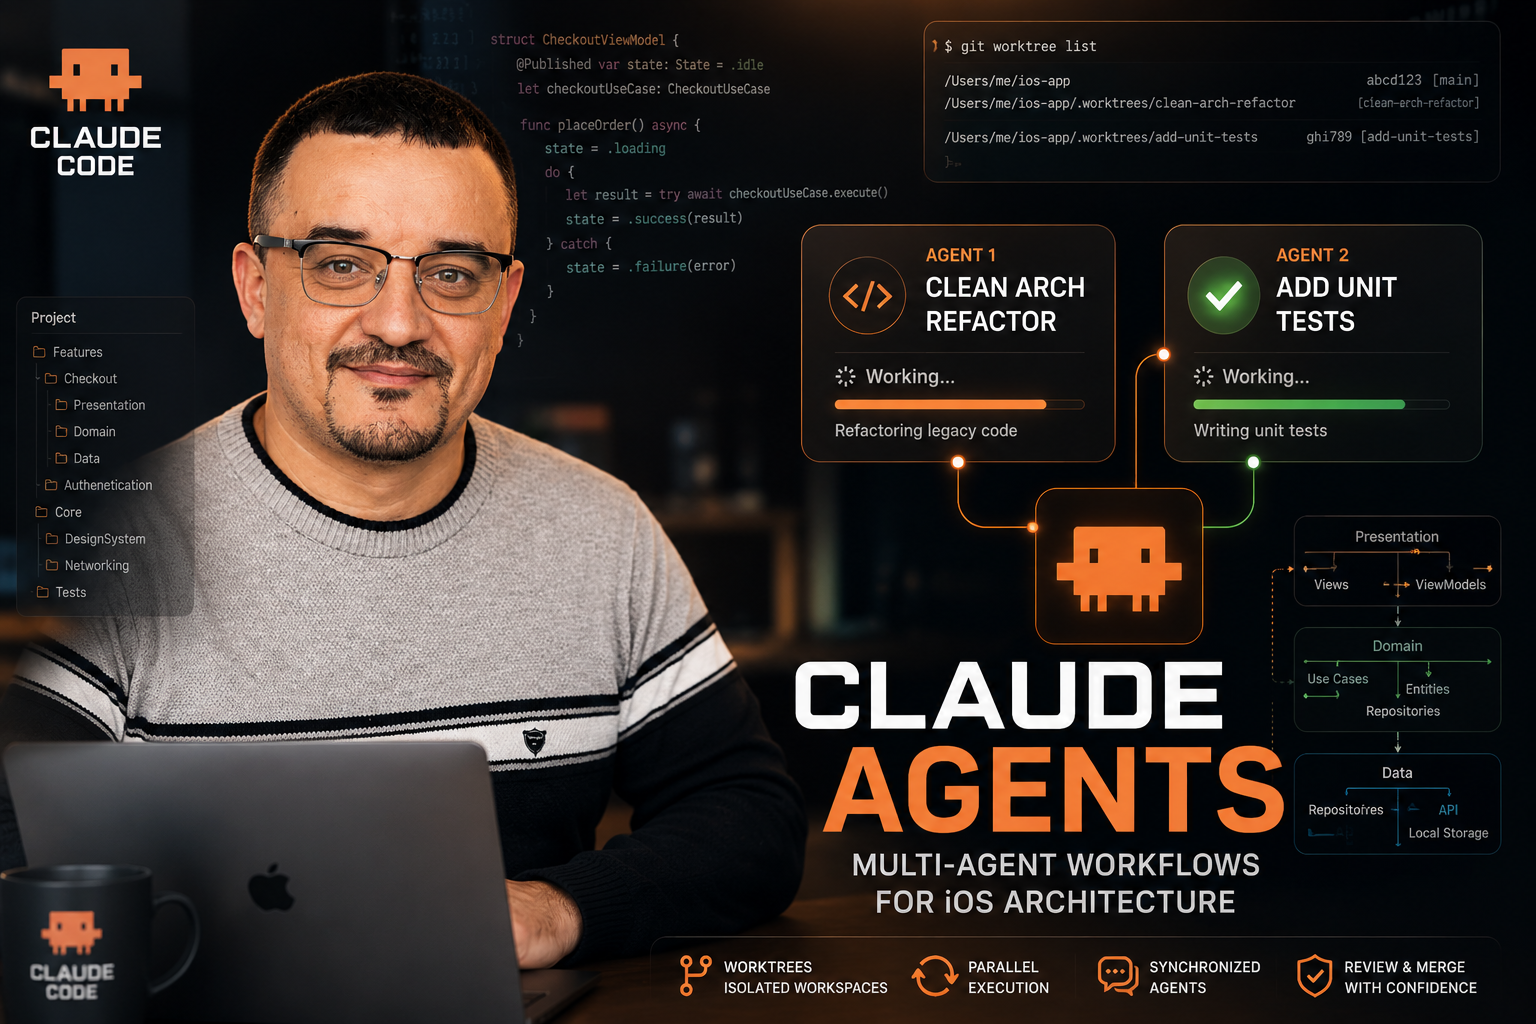
Claude Agents: Multi-Agent iOS Workflows in Claude Code

A walkthrough of Anthropic’s new Claude Agents (agent view) inside Claude Code on iOS: how to run a Clean Architecture refactor agent and a unit-testing agent in parallel on isolated Git worktrees, with the full lifecycle and synchronisation pitfalls.

May 13, 2026 · 12 min · Walid Sassi

Beyond the Prompt: Foundation Models as an Architectural Layer in iOS with Mohammad Azam

Swift Academy Podcast, Episode 10, Season 2 Beyond the Prompt: Foundation Models as an Architectural Layer in iOS Mohammad Azam on why Apple’s on-device LLM is less an AI feature and more a redefinition of where intelligence lives in your app, @Generable, @Guide, instructions, tools, and adapter-based fine-tuning, viewed through the lens of iOS layered architecture. May 3, 2026 🎧 Swift Academy Podcast · Episode 10, Season 2 · Foundation Models • On-Device LLM • iOS Architecture “Foundation Models is not a chat surface. It is a typed, on-device, structured capability you wire into your architecture, the way you wire in URLSession or SwiftData. Treat it like a chatbot and you will build bad apps. Treat it like a layer and you will build defensible ones.” ...

May 3, 2026 · 12 min · Walid Sassi
MLX Embedders, Text Embeddings on Apple Silicon with Swift

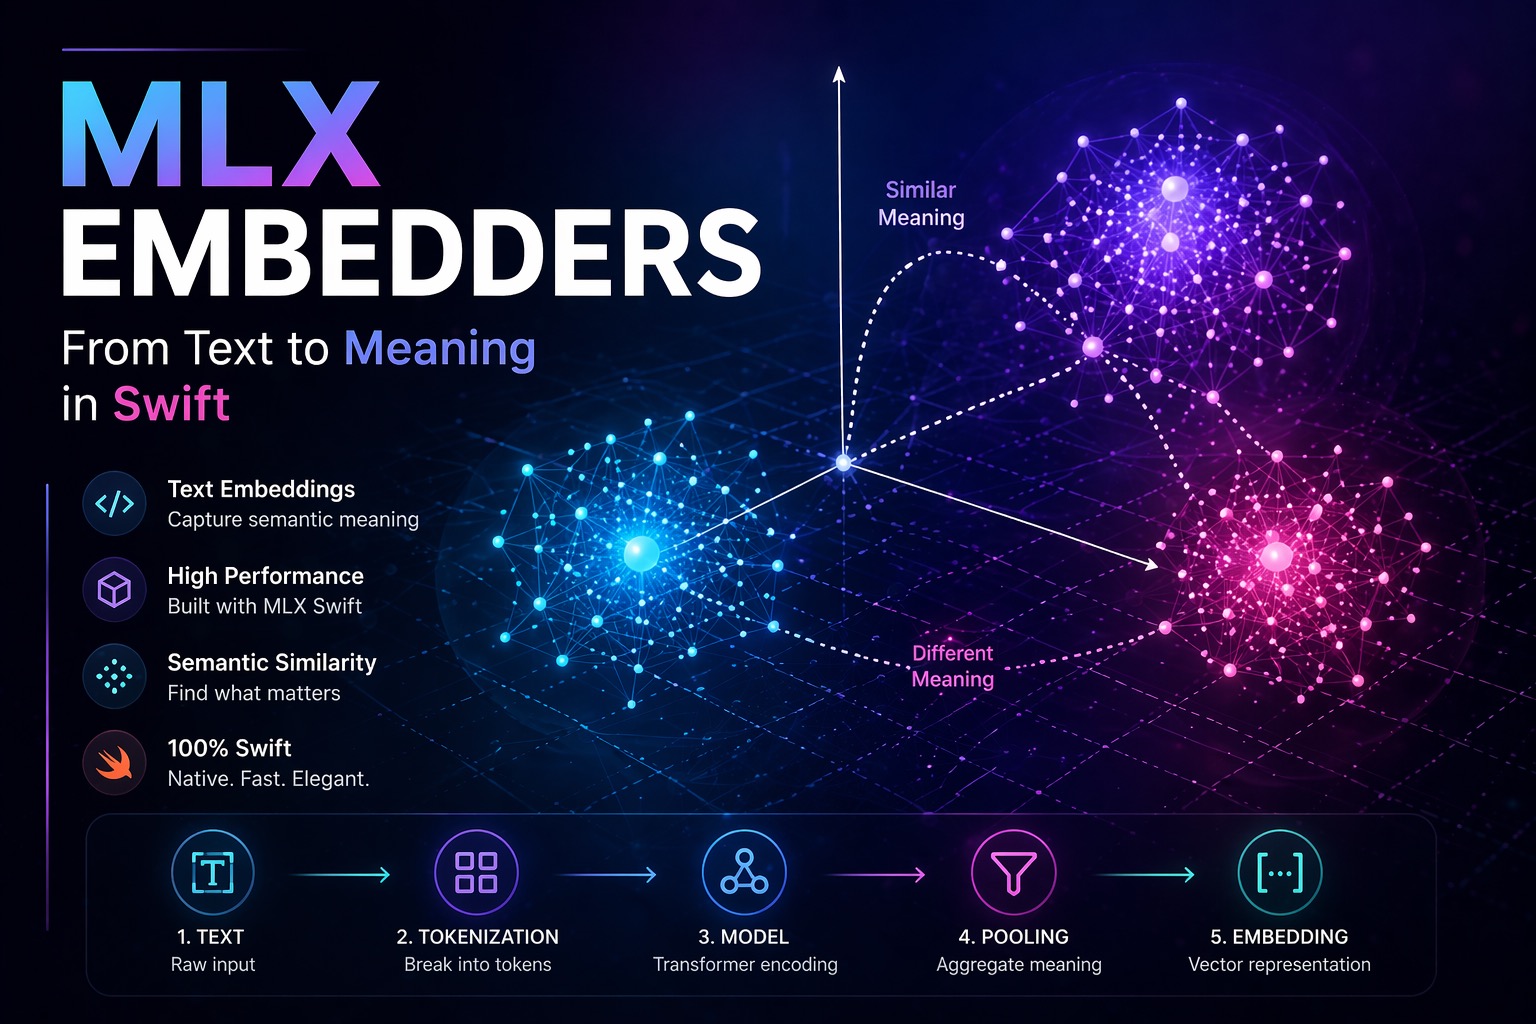
MLX Embedders in Swift: On-Device Text Embeddings for iOS

In Part 1 of this series, we built a minimal LLM inference pipeline on Apple Silicon using MLX Swift. In Part 2, we quantized a model from scratch and saw how 4-bit precision makes billion-parameter models tractable on a phone. This article introduces MLX Embedders, specifically the MLXEmbedders Swift library, and takes a different angle. Instead of generating text, we are going to encode meaning. A user types: “best hikes near a volcano.” A keyword search returns nothing useful. An embedding-based system returns exactly what they need, because it understands what the words mean, not just what they spell. That capability is what embeddings unlock, and it is the foundation of every serious AI feature in production today: semantic search, recommendation systems, RAG pipelines, and clustering. ...

April 24, 2026 · 19 min · Walid Sassi

Cupertino MCP: Local AI Tooling for Swift and iOS Development with Mihaela Mihaljević

Swift Academy Podcast, Episode 9, Season 2 Cupertino MCP: Local AI Tooling for Swift Developers How the Cupertino MCP server gives AI agents offline access to 302,000+ pages across 307 frameworks, a technical deep-dive into Model Context Protocol, local-first Swift AI development tooling, and the architecture behind a new generation of AI iOS development tools with Mihaela Mihaljević, Senior iOS Architect. April 19, 2026 🎧 Swift Academy Podcast · Episode 9, Season 2 · Model Context Protocol • Swift AI • Local Tooling “Giving an AI agent access to your full Apple documentation stack, offline, locally, without rate limits, is not a convenience. It changes the quality of what the agent can reason about. That’s the real unlock of local-first AI tooling.” ...

April 19, 2026 · 11 min · Walid Sassi
MLX Swift, On-Device Large Language Models on Apple Silicon

MLX Swift: Enabling On-Device Large Language Models on Apple Silicon

Abstract The proliferation of large-scale neural language models has, until recently, been contingent upon access to remote computational infrastructure. The architectural characteristics of Apple Silicon, most notably its unified memory subsystem, present a substantive departure from this dependency. This article examines MLX Swift, a native Swift binding to Apple’s MLX machine learning framework, as a mechanism for deploying quantized Large Language Models (LLMs) directly on consumer Apple hardware. We characterize the layered architecture of the MLX ecosystem, contrast its design philosophy with that of Apple’s Foundation Models API, and present a reference implementation demonstrating the complete inference lifecycle: model acquisition, session initialization, and autoregressive text generation. The discussion is grounded in the computational properties of unified memory and their implications for on-device inference efficiency. ...

March 31, 2026 · 13 min · Walid Sassi

Swift Concurrency Explained with Matt Massicotte

Swift Academy Podcast, Episode 8, Season 2 Swift Concurrency Explained Actors, isolation, Sendable types, and the mental model you need to reason correctly about concurrent Swift code, a technical deep-dive with Matt Massicotte, one of the most rigorous voices in the Apple platforms community. March 20, 2026 🎧 Swift Academy Podcast · Episode 8, Season 2 · Swift Concurrency • Actors • Swift 6 “The concurrency model in Swift is not just a new set of APIs. It is a new way of thinking about ownership, boundaries, and correctness. Until you have that mental model, the compiler warnings will feel arbitrary. Once you have it, they feel inevitable.” ...

March 20, 2026 · 12 min · Walid Sassi